

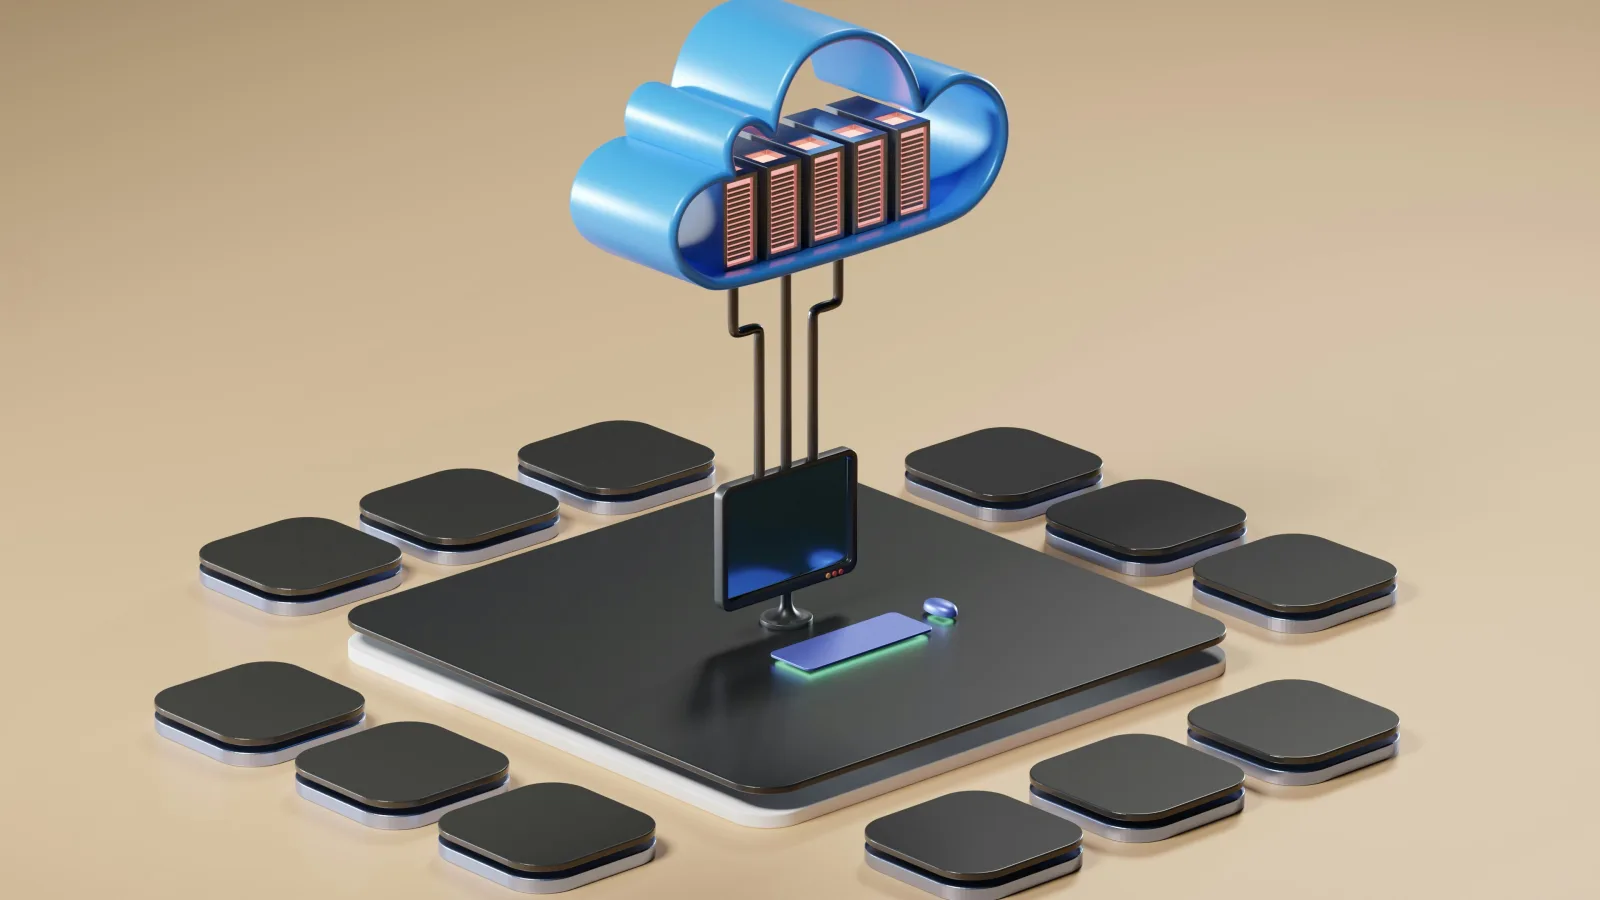
The expansion of artificial intelligence into consumer tech and enterprise systems has brought a fundamental architectural debate to the forefront: where should AI models perform their computations? Historically, complex machine learning workloads relied almost exclusively on cloud infrastructure due to massive computing requirements. However, recent advances in mobile hardware—such as specialized Neural Processing Units (NPUs) integrated into smartphones and laptops—have made local, on-device AI execution increasingly viable. Understanding the technical and security trade-offs between On-Device AI and Cloud AI is essential for users and organizations navigating modern digital privacy.
Architectural Fundamentals: How Local and Cloud AI Process Data
The core difference between On-Device AI and Cloud AI lies in where data processing takes place relative to the user's physical hardware.
- Cloud AI Architecture: Input data (text prompts, images, audio, or telemetry) is transmitted from the user's local client over an active internet connection to remote data centers. Massive high-throughput GPU server clusters perform model inference and stream the resulting data back across the network to the user's device.
- On-Device AI Architecture: The machine learning model operates directly within the local device's memory footprint. Input data is processed locally using embedded NPUs, local CPU cores, or mobile GPUs. No physical data packets leave the local hardware layer during inference.
                  +-------------------------------------------------+
                  |                CLOUD AI MODEL                   |
  Local Device --|---> (Data Sent over Internet) ---> Remote Server |
  (Client)     <---|--- (Response Returned) <--------- Data Center  |
                  +-------------------------------------------------+

                  +-------------------------------------------------+
                  |              ON-DEVICE AI MODEL                 |
  Local Device --|---> Local NPU / Embedded Memory                   |
  (Client)     <---|--- Real-Time Output (Zero Network Transmission) |
                  +-------------------------------------------------+
Read Also: How Does Apple’s Neural Engine Work? On-Device AI Explained
Latency and Processing Speed: Comparing Execution Realities
Speed and responsiveness vary significantly depending on network infrastructure and hardware execution capabilities:
- Network Latency vs. On-Chip Throughput: Cloud AI response times are bound by network latency, server queue lengths, and internet bandwidth. On-device AI eliminates transmission overhead entirely, executing inference with sub-millisecond local latency.
- Offline Resilience: On-device models function continuously regardless of network coverage, making them reliable for real-time camera processing, instant translation, and live keyboard prediction in remote environments.
- Compute Scale and Capacity: Cloud AI holds an advantage when running massive parameter models (such as large-scale multimodal models) that require hundreds of gigabytes of VRAM. Compact on-device models are quantized to balance computational footprint with memory limits.
Privacy and Data Security: Local Storage vs. Server Transmission
Data governance and user privacy represent the most significant points of divergence between the two paradigms.
Security FeatureOn-Device AICloud AIData TransmissionZero network transmission requiredRequires active SSL/TLS transmission to remote serversStorage LocationRemains encrypted on local device storageStored or logged in external cloud databasesAttack Vector ExposureLimited to local physical hardware accessExposed to cloud breaches, API vulnerabilities, and server exploitsRegulatory ComplianceSimplifies compliance with strict local data sovereignty lawsRequires complex data processing agreements and server region auditing
On-device execution isolates sensitive data—including biometric information, personal documents, and financial metrics—within local sandbox environments. Cloud-based models, while protected by server encryption, inherently create external copies of user inputs, increasing exposure to potential remote breaches or policy shifts by platform providers.
Resource Allocation, Power Consumption, and Hybrid Models
Running AI models locally requires balancing computational output with battery life and thermal limits. While local NPUs are engineered for high efficiency per watt, executing complex local workloads continuously can impact battery reserves compared to offloading processing to an external power source in a server farm.
To bridge these trade-offs, tech manufacturers are adopting Hybrid AI Architectures. Under this model, routine and privacy-sensitive queries execute locally on the device’s NPU, while highly complex tasks requiring deep contextual analysis are securely routed to encrypted cloud infrastructure.
Conclusion
Neither On-Device AI nor Cloud AI offers a single universal solution; instead, they serve complementary roles within the technology ecosystem. On-Device AI sets the benchmark for privacy, zero-latency responsiveness, and offline reliability. Conversely, Cloud AI provides unmatched raw computational power for massive AI models. As mobile hardware accelerators continue to mature, the balance will increasingly favor local processing for everyday computing, reserving cloud resources for complex analytical workloads.
General References & Sources:
- IEEE Computer Society Reports on Edge Computing & NPU Architectures
- Industry Standards on Data Privacy and Mobile AI Framework Security
- Semiconductor Performance Metrics on Local AI Inference and Power Efficiency

Komentar 0
Belum ada komentar. Jadilah yang pertama berkomentar!